Authors

Kai Waehner
Global Field CTO
Kai Waehner
Global Field CTO
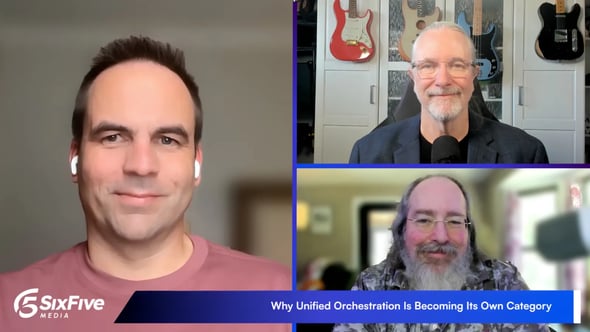
Most enterprises run a separate automation stack per domain, and often several inside one domain. Infrastructure scheduling alone usually means cron jobs, glue code, a twenty-year-old scheduler and a modern cloud scheduler running side by side. Now AI agents are being added on top. I discussed this on the Six Five webcast, and the episode is below.
Moving data between systems is a solved problem: batch, streaming and APIs have done it for twenty years. Coordinating the systems is a different layer, and most companies built it per domain (scheduling, provisioning, one business process) without connecting the pieces.
It works most days. Then a process that spans data, infrastructure, applications and business processes fails, and there is no end-to-end observability or governance. Nobody knows where the problem is, and the person who does is on vacation. Incident handling often exists only on paper or in a phone call.
An executive dashboard shows the failure but can’t act on it. An unified orchestration layer can: it sees the whole process, governs it, and decides what happens next when a step fails.
Agents show up in two ways:
Connecting the agent takes minutes. You expose the APIs through MCP, which more and more vendors already support. Governing it is the real work: what data it can access, what it is allowed to change, and how you stay compliant. An agent doesn’t ask before acting, so the controls have to sit around it.
A large bank I met recently has a process that spans infrastructure provisioning, certificate renewal, an application and a business process. An agent automates it and runs root cause analysis when something fails, so it needs access to everything. That raises two questions: what can it read, and what can it do with it?
The pattern that works:
In Kestra that transaction is the execution: the event, the AI step, the human approval and the remediation in one run with one audit trail. I showed it in the Kestra 2.0 launch demo.
It also has to work across models. Large organizations already mix providers for sovereignty and cost, sometimes several US providers plus open models. Governance at the orchestration layer stays the same when you swap the model underneath.
Sovereignty, data privacy and security don’t come for free with any product. Decide them before you evaluate tools:
Kestra separates the control plane, where you define orchestration, from the workers that run it. Workers run where the data is: next to Snowflake or Databricks in the cloud, next to a mainframe and existing schedulers in your data center, or fully air-gapped in a factory. If you bolt these requirements on after the fact for agentic AI, the project fails.
JPMorgan Chase’s cybersecurity teams use Kestra to collect threat intelligence from dozens of external feeds, such as malicious domains and leaked credentials, analyze it, and deliver it to fraud detection teams and business units in near real time. The pipeline handles more than 4,000 API pulls a week for over 100 users. Failed pulls are retried, and urgent alerts go out fast.
The right order for any project is the business problem first, then the architecture, then the technical details.
Watch the full episode on Six Five Media, or see one execution carry an agent, a human decision and the remediation in the Kestra 2.0 launch recap.
Stay up to date with the latest features and changes to Kestra