Bulk Load CSV Data into PostgreSQL Using COPY for Fast ETL Ingestion
Bulk load a CSV file into PostgreSQL with the native COPY protocol for fast, reliable ETL ingestion.


One platform for data, AI, and business-critical workflows.


Kestra has streamlined our data processes, reduced costs, and significantly enhanced our scalability and efficiency. It has truly been a critical asset in our digital transformation journey.
Reported by teams switching from Airflow to Kestra in production.*
Self-hosted Kestra runs on minimal infrastructure. No overprovisioned workers or complex component scaling. Deploy on your existing Kubernetes cluster or a single VM.
Eliminate weeks of operational overhead. No upgrades breaking plugins, no dependency conflicts, no executor tuning. Ship pipelines, not infrastructure.
Many orchestrators lock enterprise features behind expensive managed plans. Kestra delivers them in open source or flexible commercial licensing.
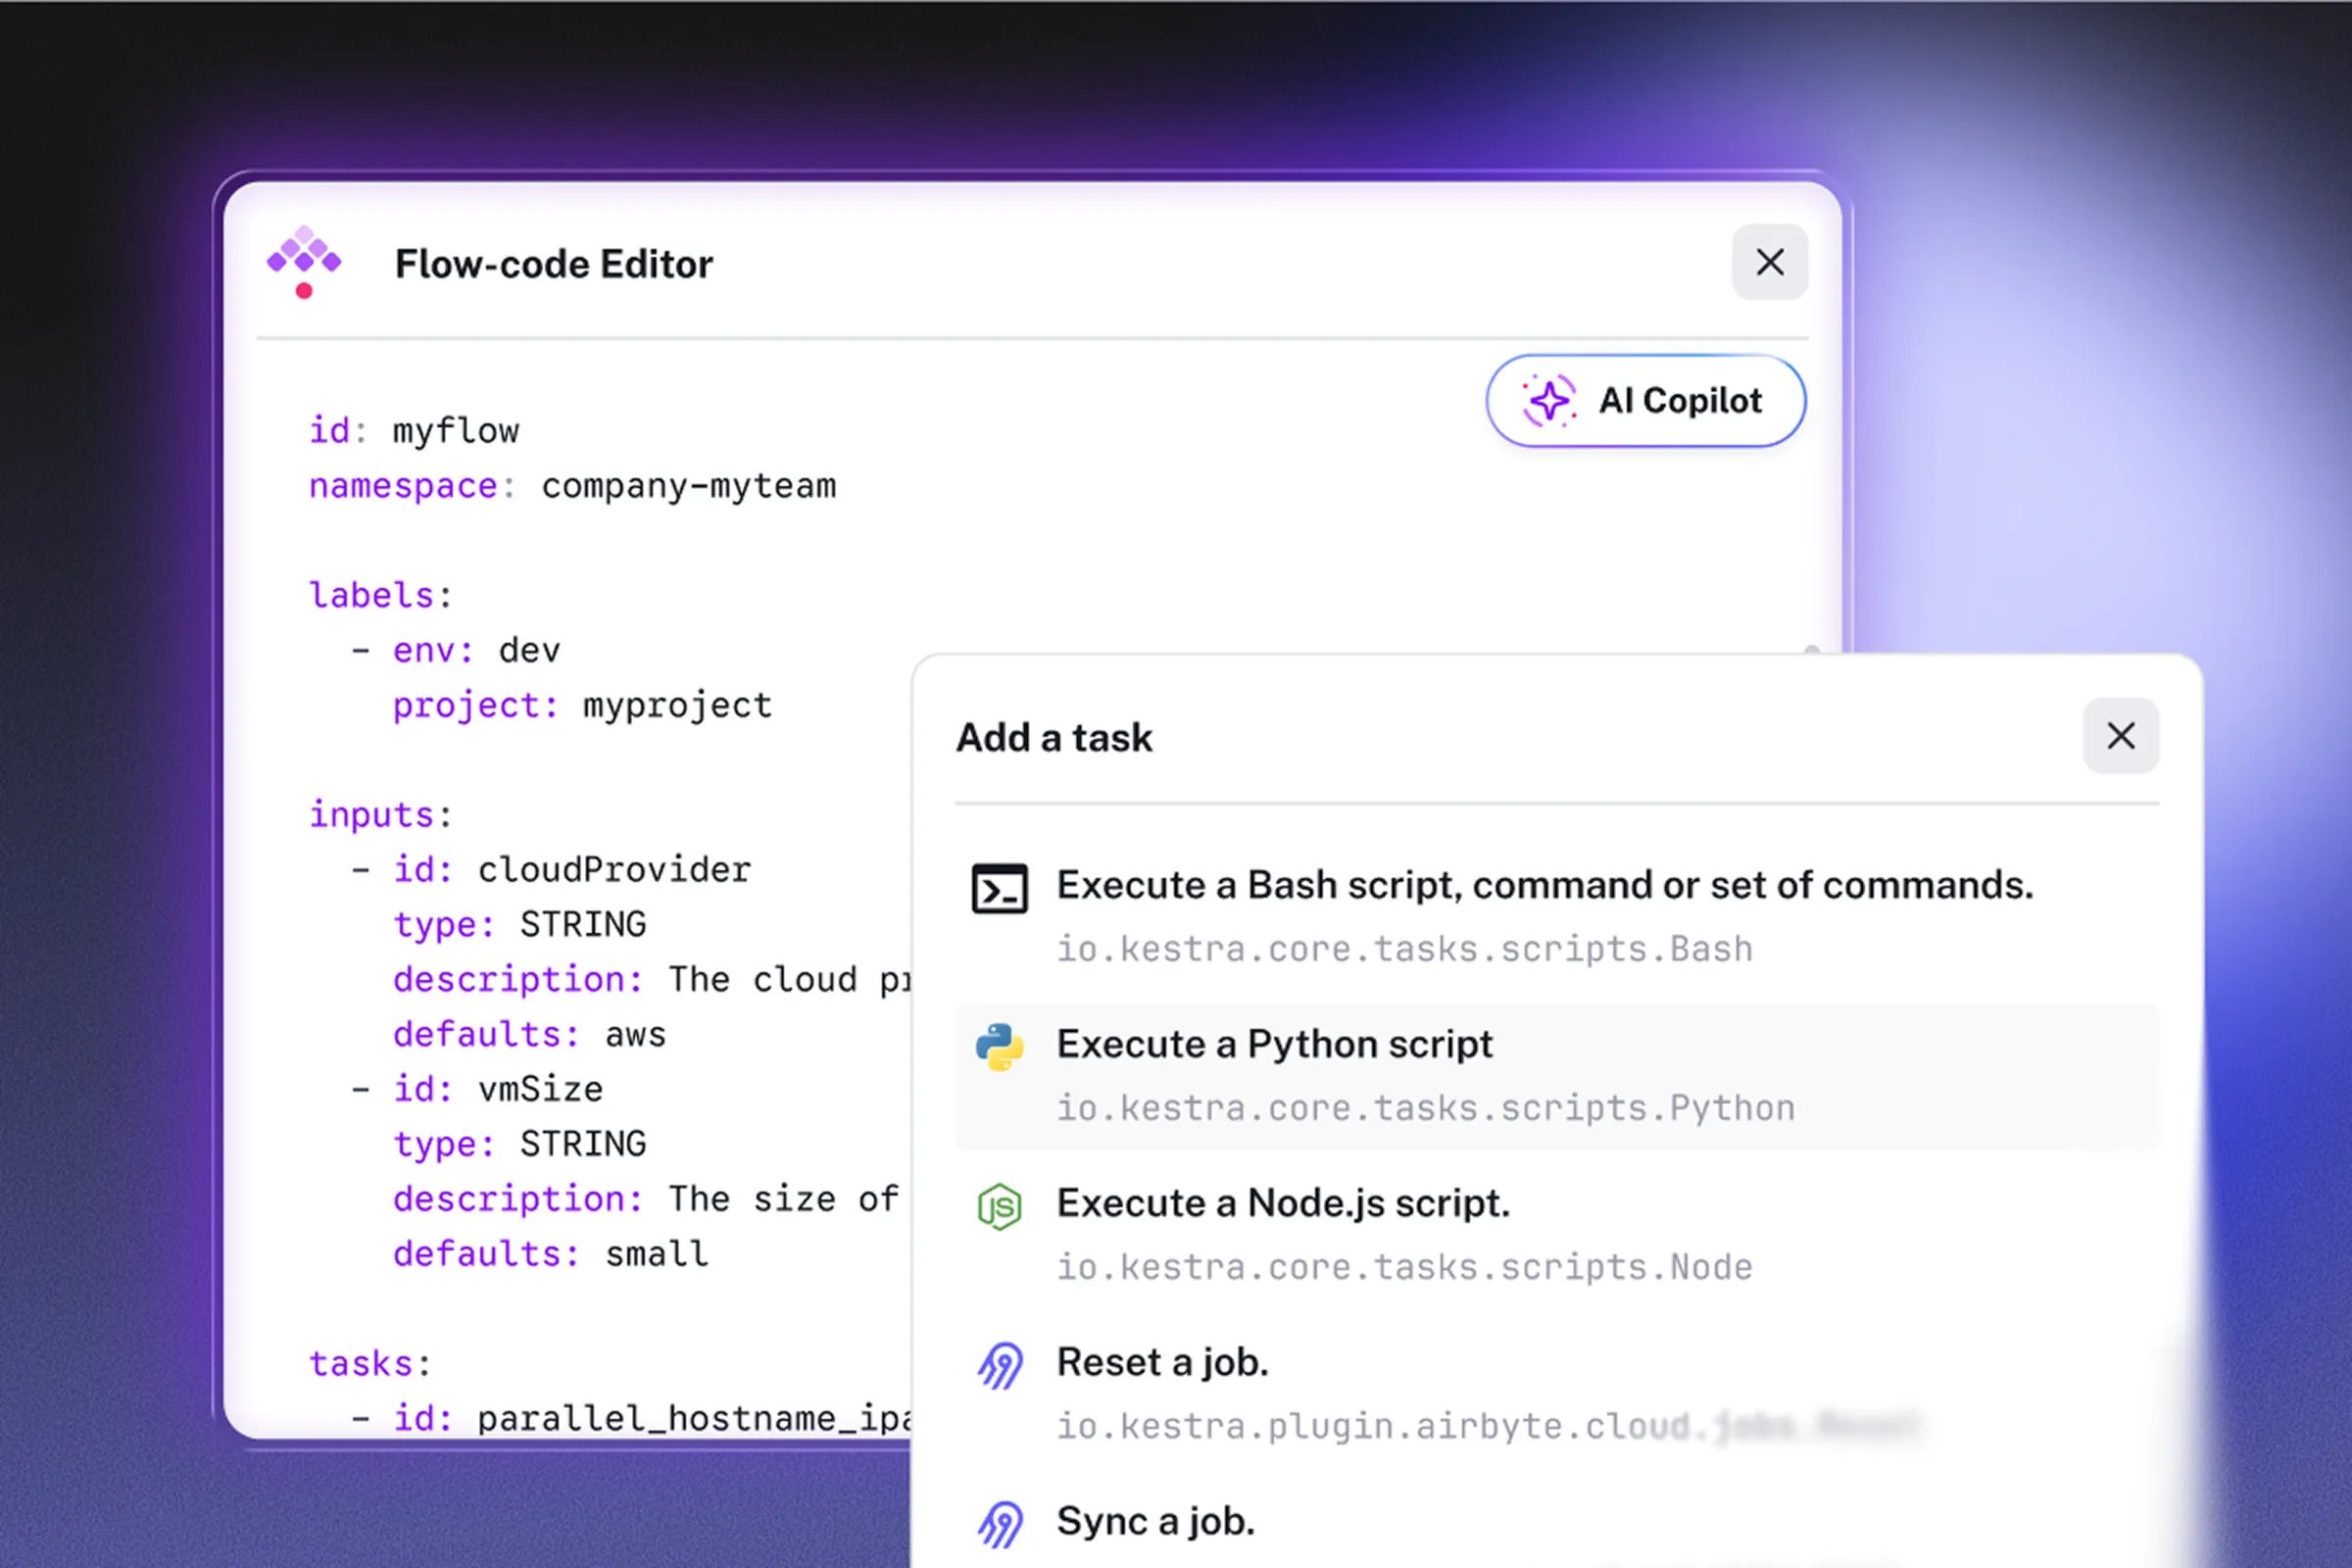
Kestra Copilot turns natural language into working pipelines using dbt, Airbyte, Spark, Snowflake, BigQuery, Databricks, and2,600+ plugins.
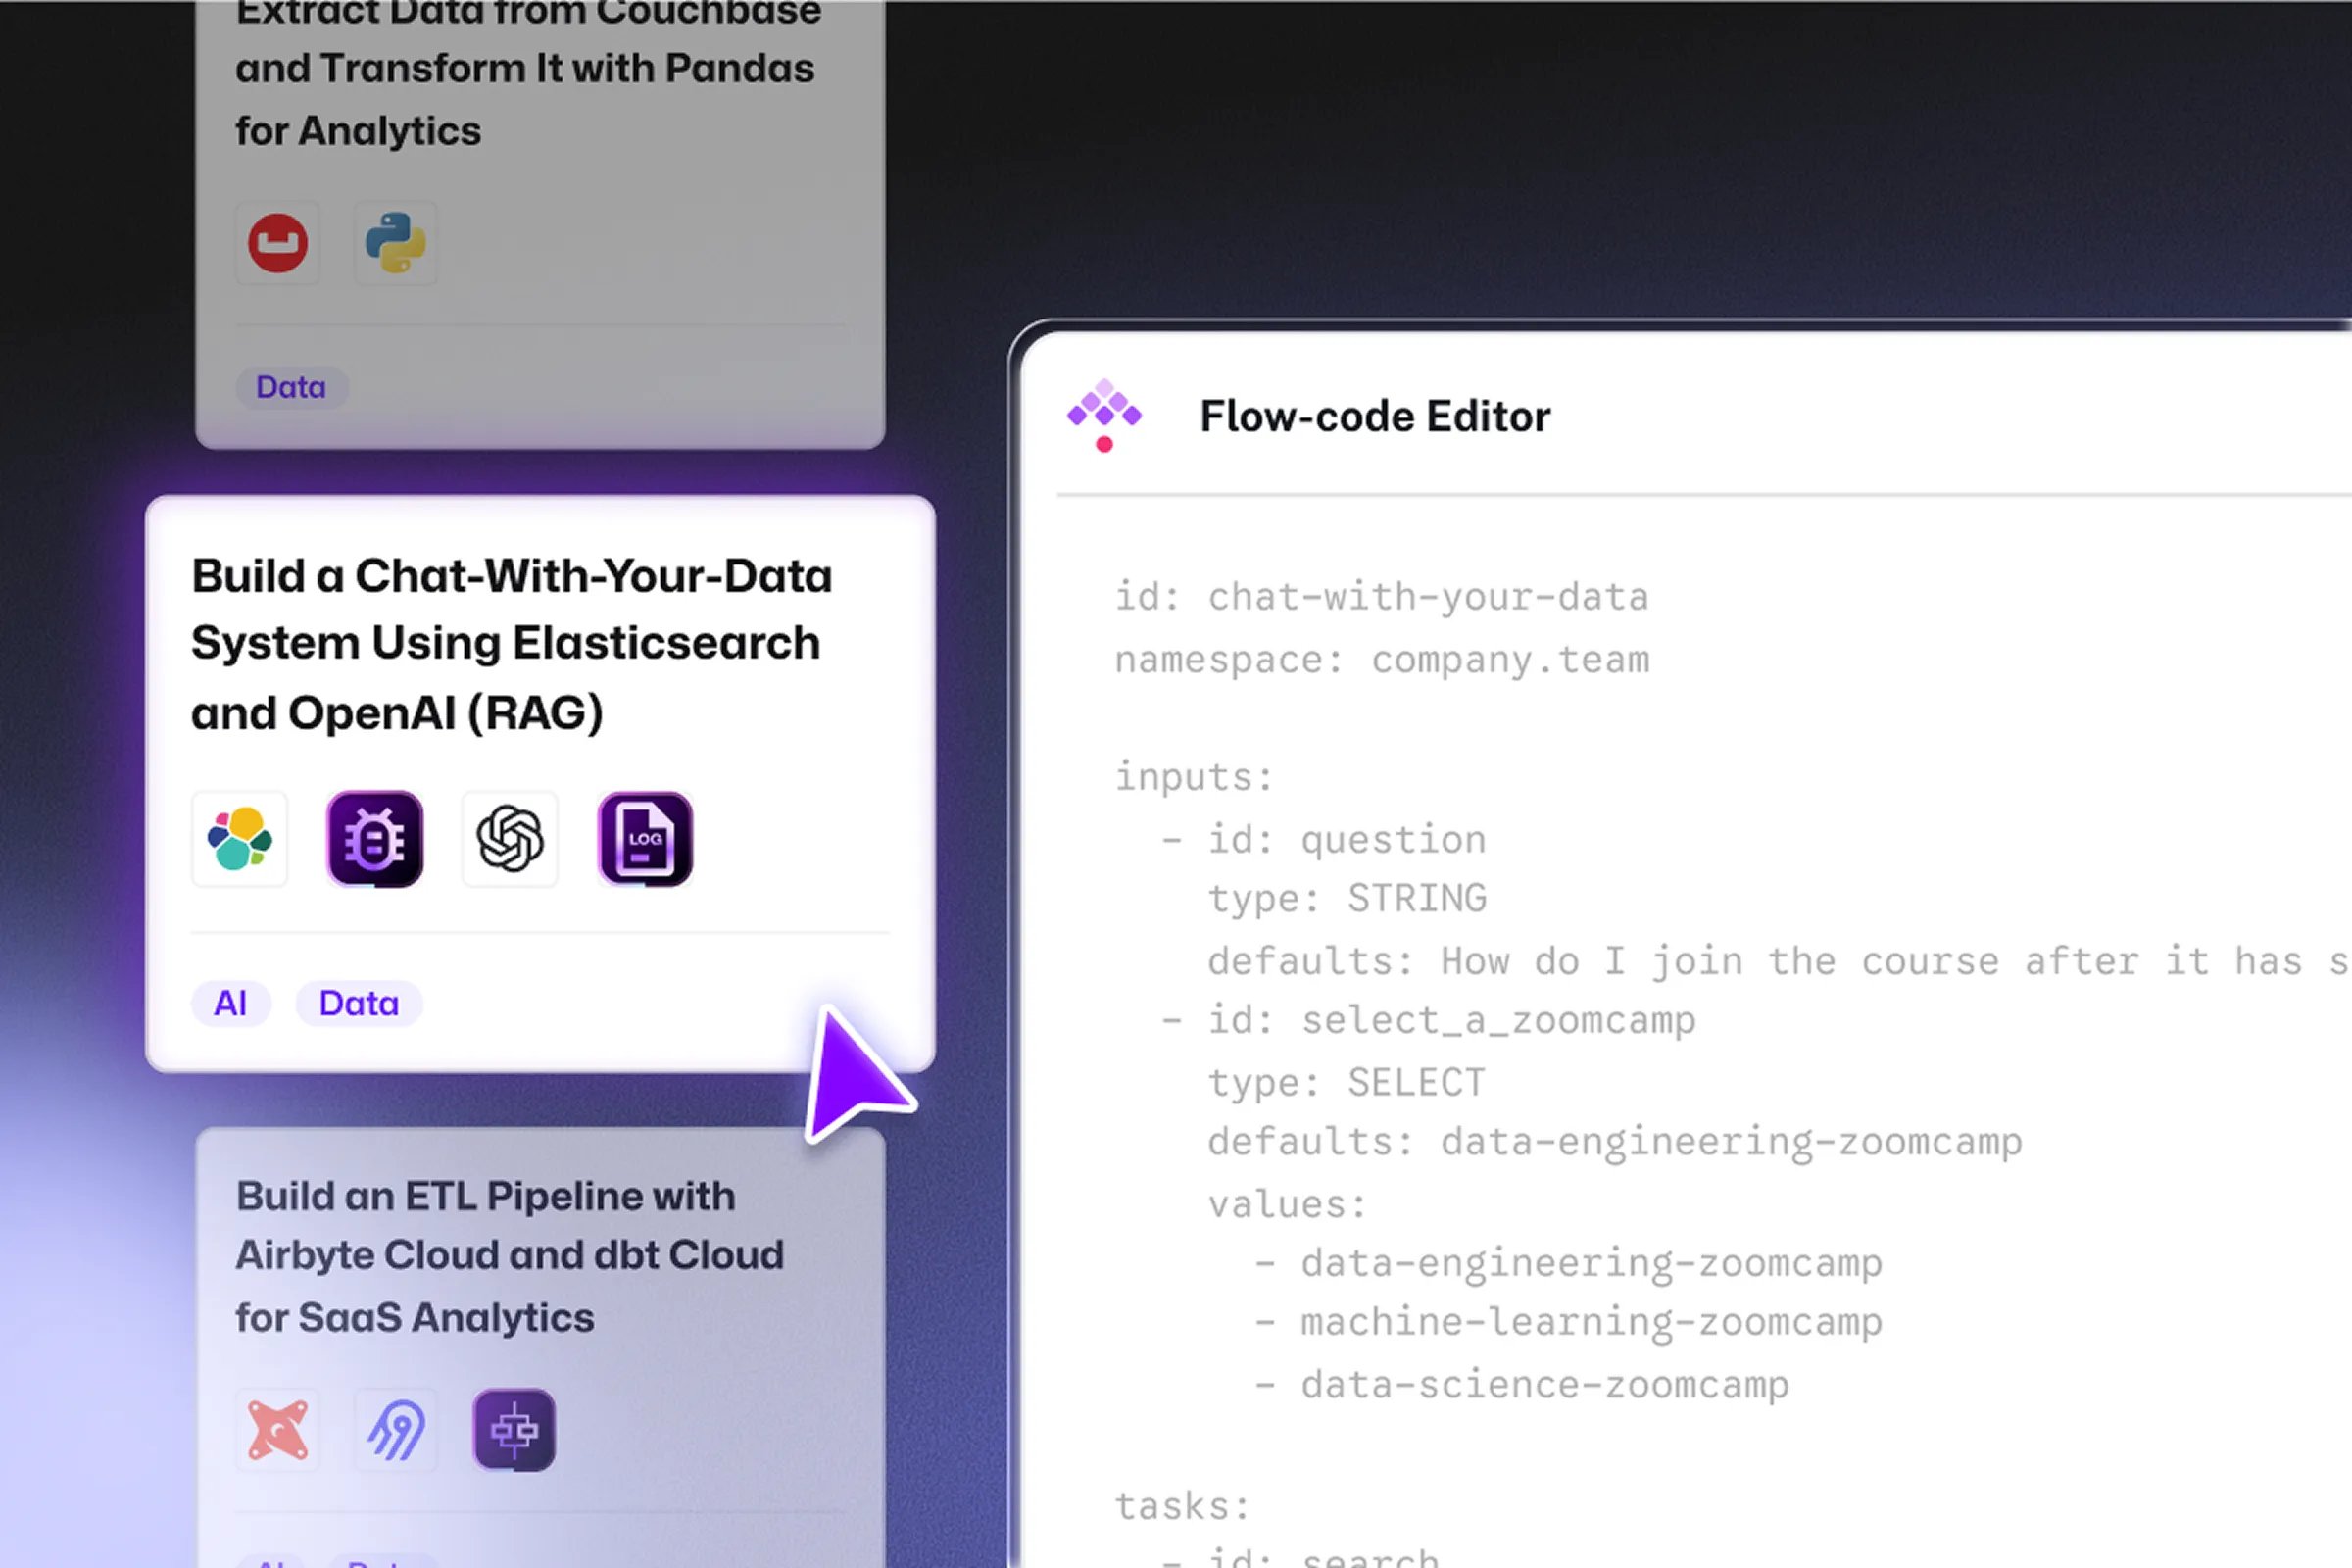
Pick from our production-ready Blueprints for common data workflows. Copy, customize, deploy in minutes.
Bulk load a CSV file into PostgreSQL with the native COPY protocol for fast, reliable ETL ingestion.
Query a Cosmos DB container for documents that should have expired but are still present, classify the run by violation count, alert Slack, and optionally delete them and verify.


Catch Couchbase GSI indexes stuck in deferred or pending after a defer_build migration, build them behind a dry-run gate, then re-read system:indexes to confirm every one is online.


Find Couchbase keyspaces carrying two or more online GSI indexes on the same keys, condition and partition, keep one per group, then drop the surplus behind a dry-run gate and a human approval and re-read system:indexes to prove it landed.


Fire whenever a N1QL compliance query returns a violating document, alert Slack with the real document ids, and log a governance audit trail.

Audit Couchbase GSI secondary indexes for offline, building, or degraded states with automated Slack alerts.
Find Couchbase N1QL requests whose elapsed time is over a threshold in system:active_requests, cancel each by requestId behind a dry-run gate and a human approval, then re-read system:active_requests and fail the run if any request is still over the threshold.

Query a Couchbase NoSQL bucket with N1QL and reshape the results in Python with Pandas, all in one orchestrated flow.

Scan a Couchbase collection for documents nearing TTL expiry and either log a dry-run triage report or quarantine them, with a Slack report per run.
Audit CouchDB database fragmentation and document conflicts, prune losing revisions with approval gates, trigger compaction, and verify recovery.


Audits CouchDB /_active_tasks for continuous replication lag and automates database compaction.
Audits CrateDB sys.shards for unassigned primary and replica partitions and automates cluster rerouting.
Ingest dynamic URLs, run Crawl4AI with headless Chromium stealth, extract token-optimized Markdown, and sink clean text to storage.
Query a remote CSV with DuckDB on a weekly schedule and post the sales metrics straight to Slack.

Parse CSV records, split them into ION chunks, and stage three chunks at a time. Replace the live PostgreSQL snapshot only after every row passes validation.


Download a CSV from any public URL and bulk-load it into PostgreSQL using the fast native COPY protocol.

Audits Cube.js semantic layer pre-aggregation partitions and build status, detects refresh failures, and dispatches actionable Slack incident alerts.
Fetch the daily USD/INR exchange rate, extract it with DuckDB, and branch on a threshold with an If task.

Concurrently extracts user feedback using DuckDB SQL, verifies API uptime, and conditionally routes telemetry.


Trigger a Dagster job, wait for a terminal state, alert Slack when it does not come back SUCCESS, and optionally launch one fresh retry run.

Bulk load a CSV file into PostgreSQL with the native COPY protocol for fast, reliable ETL ingestion.
Query a Cosmos DB container for documents that should have expired but are still present, classify the run by violation count, alert Slack, and optionally delete them and verify.
Catch Couchbase GSI indexes stuck in deferred or pending after a defer_build migration, build them behind a dry-run gate, then re-read system:indexes to confirm every one is online.
Find Couchbase keyspaces carrying two or more online GSI indexes on the same keys, condition and partition, keep one per group, then drop the surplus behind a dry-run gate and a human approval and re-read system:indexes to prove it landed.
Fire whenever a N1QL compliance query returns a violating document, alert Slack with the real document ids, and log a governance audit trail.
Audit Couchbase GSI secondary indexes for offline, building, or degraded states with automated Slack alerts.

Fivetran

Snowflake

Databricks

Azure

DBT

Airbyte

MongoDB

Cassandra

PostgreSQL

MySQL

Redshift

BigQuery

ClickHouse

Redis

Elasticsearch

Kafka

Pulsar

RabbitMQ
Fivetran
Snowflake
Databricks
Azure
DBT
Airbyte
MongoDB
Cassandra
PostgreSQL
MySQL
Redshift
BigQuery
ClickHouse
Redis
Elasticsearch
Kafka
Pulsar
RabbitMQ
| Legacy orchestrators (e.g. Airflow) | Modern alternatives | Why this matters | ||
|---|---|---|---|---|
| Workflow definition | Declarative YAML | Python DAGs | Python SDKs with custom abstractions | Your existing scripts work as-is. Zero migration tax. |
| Languages supported | Any (Python, SQL, R, Bash, etc.) | Python only | Python only | Analysts use SQL, engineers use Python, ops use Bash. |
| Time to first pipeline | < 5 minutes | 1-2 hours | 30-60 minutes | Ship 10x faster. Deliver value day one. |
| Learning curve | YAML (immediate) | Framework + infrastructure setup | Framework concepts and abstractions | Junior engineers ship pipelines their first day. |
| Live DAG preview | Yes, real-time | No (deploy to see) | No (deploy to see) | See changes instantly. No deploy-to-preview cycles. |
| Event-driven triggers | Native, unlimited | Limited sensors (polling-based) | Yes, native support | React in seconds, not minutes, with real-time workflows. |
| Execution isolation | Containers per task | Shared workers | Configurable | No dependency conflicts. Ship fearlessly. |
| Built-in observability | Metrics, logs, tracing included | Requires manual setup | Setup required or cloud-dependent | Debug in minutes with full visibility out of the box. |
| Multi-language team support | SQL, Python, Bash all native | Python wrappers required | Python wrappers required | Everyone contributes using their native tools. |
| Scope beyond data | AI, infra, business workflows | Data pipelines only | Data pipelines primary focus | Future-proof your platform with one orchestrator for everything. |
| Enterprise deployment | Self-hosted or cloud | Self-managed infrastructure | Self-hosted or cloud-first | 50%+ lower TCO. Less infrastructure, less ops time. |
| Migration path | Incremental (run Airflow + Kestra in parallel) | N/A | Requires full rewrite | Move pipelines one by one, no big-bang cutover. |

Join 500+ data teams who’ve modernized their orchestration with Kestra.
Find answers to your questions right here, and don't hesitate to Contact Us if you couldn't find what you're looking for.